

3.1 · The dry run — required
Prompt
You’ll see: Ana discover your schema, diff it against the ontology, and hand you a precise list of fixes — table backings, column names, and the all-important earned-vs-written premium question. (The ready-made version lives in
validation/dry-run-prompt.md.)3.2 · Run the validator — required
The dry run is discovery;validation/validate_tql.py is the mechanical gate. It verifies every governed surface against your warehouse: each logical name resolves, each referenced column exists, each query compiles. Ana runs it for you — no terminal needed:
Prompt
You’ll see: the typo’d-backing, wrong-alias, and missing-column bug classes caught here — instead of surfacing as wrong numbers in front of stakeholders.
Prefer the terminal? — The same gate runs locally:
python3 validation/validate_tql.py (static — no warehouse needed) · --check-sql (paste the output into Ana: rows = missing columns) · --dsn "<dsn>" --explain (live column check + compile test).3.3 · Apply the fixes as a PR — required
Prompt
You’ll see: Ana edit the files and open a reviewable PR in your repo. Every physical table name lives in one place (
ontology/schema.tql) — re-point it and the metric logic stays put. The join keys the surfaces rely on are policy_id, policyholder_id, and claim_id.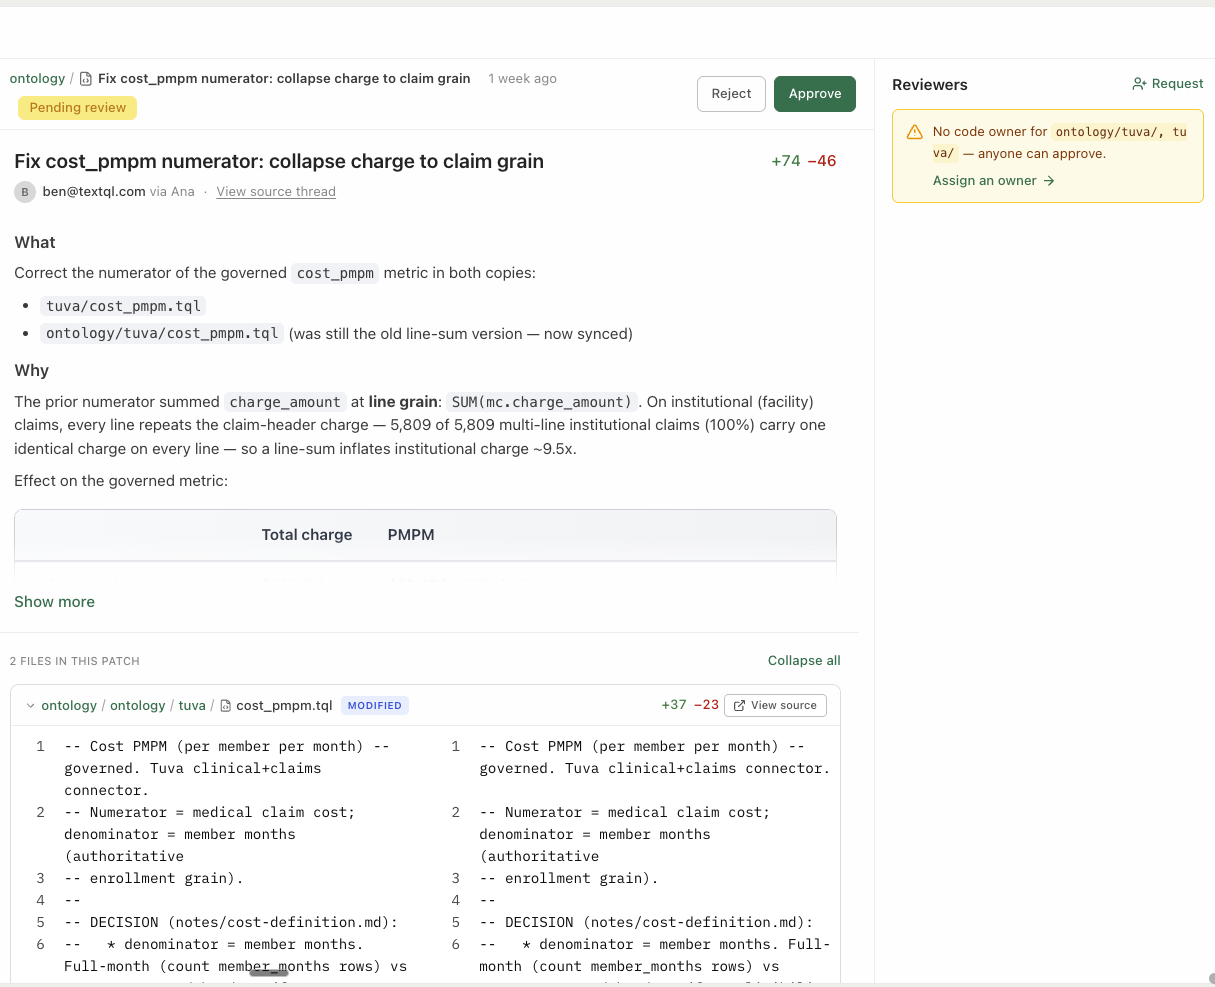
Validation lands as a reviewable PR — not silent edits.
Why this step matters — Every carrier’s warehouse differs from the reference shape somewhere — a renamed column, a missing table, a different grain. Finding those before you trust a number is the difference between a defensible loss ratio and a debugging session in front of the actuary.
3.4 · Decide your grain & verify your joins — required
Insurance data fans out across several grains — policy vs. coverage vs. claim vs. transaction — and joining across them carelessly multiplies counts. Settling this is the single most important decision in this module, and it’s a prompt:| Table | Grain | Count this for… |
|---|---|---|
policy | 1 / policy | policies in force, retention, new business |
coverage | 1 / coverage line (many per policy) | peril/limit exposure — not policy counts |
premium_earned | 1 / policy / month | earned premium (sum the series over the window) |
claim | 1 / claim | frequency, severity, loss ratio, reserves |
claim_transaction | 1 / payment or reserve move | loss development only |
Prompt
You’ll see: the grain decision made and written down before anything gets edited — it shapes every count downstream. The trap to confirm: a policy fans out into many coverage lines, and a claim into many transactions; anchor policy counts on
policy and claim counts on distinct claim_id.Prompt
You’ll see: a join-by-join verdict list plus a basis check — because loss ratio needs incurred losses and accident-year dating, and a paid-only or report-date warehouse changes the number.
Prompt
You’ll see: the enumerations the validator can’t know —
status = 'open', the renewal flag, the LOB and cause-of-loss spellings — corrected from your real data instead of assumed.The full checklist — This module covers the core;
MIGRATION.md is the complete 8-step re-point (discover → grain → schema.tql → identity → validator → literals → governance → glossary → goldens). Half a day with warehouse access; most of it is verification, not editing.Written-only premium? — If your warehouse stores premium only as written-at-inception (no monthly earned series), the ratios can’t sum earned directly — you must earn it pro-rata over
effective_date → expiration_date first. Flag it in the dry run; notes/premium-definition.md has the derivation. This is the difference between a correct loss ratio and one that flatters a growing book.✅ Checkpoint
- Ana produced a concrete mismatch list (or confirmed a clean match)
- The policy/coverage/claim/transaction grain is decided and written down
- The fixes landed as a PR you can review — not silent edits — and you merged it (or know who reviews it)